

Algorithms for Efficient Computation of Convolution
Convolution is an important mathematical tool in both fields of signal and image processing. It is employed in filtering, denoising, edge detection, correlation, compression, deconvolution, simulation, and in many other applications. Although the concept of convolution is not new, the efficient computation of convolution is still an open topic. As the amount of processed data is constantly increasing, there is considerable request for fast manipulation with huge data. Moreover, there is demand for fast algorithms which can exploit computational power of modern parallel architectures.
Adaptive distributed noise reduction for speech enhancement in wireless acoustic sensor networks
An adaptive distributed noise reduction algorithm for speech enhancement is considered, which operates in a wireless acoustic sensor network where each node collects multiple microphone signals. In previous work, it was shown theoretically that for a stationary scenario, the algorithm provides the same signal estimators as the centralized multi-channel Wiener filter, while significantly compressing the data that is transmitted between the nodes. Here, we present simulation results of a fully adaptive implementation of the algorithm, in a non-stationary acoustic scenario with a moving speaker and two babble noise sources. The algorithm is implemented using a weighted overlap-add technique to reduce the overall input-output delay. It is demonstrated that good results can be obtained by estimating the required signal statistics with a long-term forgetting factor without downdating, even though the signal statistics change along with the iterative filter updates. It is also demonstrated that simultaneous node updating provides a significantly smoother and faster tracking performance compared to sequential node updating.
Introduction of C Programming for DSP Applications
Appendix C of the book : Real-Time Digital Signal Processing: Implementations, Application and Experiments with the TMS320C55X
Reduced-Delay IIR Filters
This document describes a straightforward method to significantly reduce the number of necessary multiplies per input sample of traditional IIR lowpass and highpass digital filters.
Evaluation of a Floating Point Acoustic Echo Canceller Implementation
This master thesis consists of implementation and evaluation of an AEC, Acoustic Echo Canceller, algorithm in a floating-point architecture. The most important question this thesis will try to answer is to determine benefits or drawbacks of using a floating-point architecture, relative a fixed-point architecture, to do AEC. In a telephony system there is two common forms of echo, line echo and acoustic echo. Acoustic echo is introduced by sound emanating from a loudspeaker, e.g. in a handsfree or speakerphone, being picked up by a microphone and then sent back to the source. The problem with this feedback is that the far-end speaker will hear one, or multiple, time-delayed version(s) of her own speech. This time-delayed version of speech is usually perceived as both confusing and annoying unless removed by the use of AEC. In this master thesis the performance of a floating-point version of a normalized least-mean-square AEC algorithm was evaluated in an environment designed and implemented to approximate live telephony calls. An instruction-set simulator and assembler available at the initiation of this master thesis were extended to enable; zero-overhead loops, modular addressing, post-increment of registers and register-write forwarding. With these improvements a bit-true assembly version was implemented capable of real-time AEC requiring 15 million instructions per second. A solution using as few as eight mantissa bits, in an external format used when storing data in memory, was found to have an insignificant effect on the selected AEC implementation’s performance. Due to the relatively low memory requirement of the selected AEC algorithm, the use of a small external format has a minor effect on the required memory size. In total this indicates that the possible reduction of the memory requirement and related energy consumption, does not justify the added complexity and energy consumption of using a floating-point architecture for the selected algorithm. Use of a floating-point format can still be advantageous in speech-related signal processing when the introduced time delay by a subband, or a similar frequency domain, solution is unacceptable. Speech algorithms that have high memory use and small introduced delay requirements are a good candidate for a floating-point digital signal processor architecture.
A DSP Implementation of OFDM Acoustic Modem
The success of multicarrier modulation in the form of OFDM in radio channels illuminates a path one could take towards high-rate underwater acoustic communications, and recently there are intensive investigations on underwater OFDM. In this paper, we implement the acoustic OFDM transmitter and receiver design of [4, 5] on a TMS320C6713 DSP board. We analyze the workload and identify the most time-consuming operations. Based on the workload analysis, we tune the algorithms and optimize the code to substantially reduce the synchronization time to 0.2 seconds and the processing time of one OFDM block to 1.7 seconds on a DSP processor at 225 MHz. This experimentation provides guidelines on our future work to reduce the per-block processing time to be less than the block duration of 0.23 seconds for real time operations.
LOW-RESOURCE DELAYLESS SUBBAND ADAPTIVE FILTER USING WEIGHTED OVERLAP-ADD
A delayless structure targeted for low-resource implementation is proposed to eliminate filterbank processing delays in subband adaptive filters (SAFs). Rather than using direct IFFT or polyphase filterbanks to transform the SAFs back into the time-domain, the proposed method utilizes a weighted overlap-add (WOLA) synthesis. Low-resource real-time implementations are targeted and as such do not involve long (as long as the echo plant) FFT or IFFT operations. Also, the proposed approach facilitates time distribution of the adaptive filter reconstruction calculations crucial for efficient real-time and hardware implementation. The method is implemented on an oversampled WOLA filterbank employed as part of an echo cancellation application. Evaluation results demonstrate that the proposed implementation outperforms conventional SAF systems since the signals used in actual adaptive filtering are not distorted by filterbank aliasing. The method is a good match for partial update adaptive algorithms since segments of the time-domain adaptive filter are sequentially reconstructed and updated.
Efficient arithmetic for high speed DSP implementation on FPGAs
The author was sponsored by EnTegra Ltd, a company who develop hardware and software products and services for the real time implementation of DSP and RF systems. The field programmable gate array (FPGA) is being used increasingly in the field of DSP. This is due to the fact that the parallel computing power of such devices is ideal for today’s truly demanding DSP algorithms. Algorithms such as the QR-RLS update are computationally intensive and must be carried out at extremely high speeds (MHz). This means that the DSP processor is simply not an option. ASICs can be used but the expense of developing custom logic is prohibitive. The increased use of the FPGA in DSP means that there is a significant requirement for efficient arithmetic cores that utilises the resources on such devices. This thesis presents the research and development effort that was carried out to produce fixed point division and square root cores for use in a new Electronic Design Automation (EDA) tool for EnTegra, which is targeted at FPGA implementation of DSP systems. Further to this, a new technique for predicting the accuracy of CORDIC systems computing vector magnitudes and cosines/sines is presented. This work allows the most efficient CORDIC design for a specified level of accuracy to be found quickly and easily without the need to run lengthy simulations, as was the case before. The CORDIC algorithm is a technique using mainly shifts and additions to compute many arithmetic functions and is thus ideal for FPGA implementation.
Decoding Ogg Vorbis Audio with The C6416 DSP, using a custom made MDCT core on FPGA
Ogg Vorbis is a fairly new and growing audio format, often used for online distribution of music and internet radio stations for streaming audio. It is considered to be better than MP3 in both quality and compression and in the same league as for example AAC. In contrast with many other formats, like MP3 and AAC, Ogg Vorbis is patent and royalty free. The purpose of this thesis project was to investigate how the C6416 DSP processor and a Stratix II FPGA could be connected to each other and work together as co-processors and using an Ogg Vorbis decoder as implementation example. A fixed-point decoder called Tremor (developed by Xiph.Org the creator of the Vorbis I specification), has been ported to the DSP processor and an Ogg Vorbis player has been developed. Tremor was profiled before performing the software / hardware partitioning to decide what parts of the source code of Tremor that should be implemented in the FPGA to off-load and accelerate the DSP.
Implementation of Elementary Functions for a Fixed Point SIMD DSP Coprocessor
This thesis is about implementing the functions for reciprocal, square root, inverse square root and logarithms on a DSP platform. A multi-core DSP platform that consists of one master processor core and several SIMD coprocessor cores is currently being designed by a team at the Computer Engineering Department of Linköping University. The SIMD coprocessors’ arithmetic logic unit (ALU) has 16 multipliers to support vector multiplication instructions. By efficiently using the 16 multipliers, it is possible to evaluate polynomials very fast. The ALU does not have (hardware) support for floating point arithmetic, so the challenge is to get good precision by using fixed point arithmetic. Precise and fast solutions to implement the mathematical functions are found by converting the fixed point input to a soft floating point format before polynomial approximation, choosing a polynomial based on an error analysis of the polynomial approximation, and using Newton-Raphson or Goldschmidt iterations to improve the precision of the polynomial approximations. Finally, suggestions are made of changes and additions to the instruction set architecture, in order to make the implementations faster, by efficiently using the currently existing hardware.
Algorithms for Efficient Computation of Convolution
Convolution is an important mathematical tool in both fields of signal and image processing. It is employed in filtering, denoising, edge detection, correlation, compression, deconvolution, simulation, and in many other applications. Although the concept of convolution is not new, the efficient computation of convolution is still an open topic. As the amount of processed data is constantly increasing, there is considerable request for fast manipulation with huge data. Moreover, there is demand for fast algorithms which can exploit computational power of modern parallel architectures.
Digital Signal Processor Fundamentals and System Design
Digital Signal Processors (DSPs) have been used in accelerator systems for more than fifteen years and have largely contributed to the evolution towards digital technology of many accelerator systems, such as machine protection, diagnostics and control of beams, power supply and motors. This paper aims at familiarising the reader with DSP fundamentals, namely DSP characteristics and processing development. Several DSP examples are given, in particular on Texas Instruments DSPs, as they are used in the DSP laboratory companion of the lectures this paper is based upon. The typical system design flow is described; common difficulties, problems and choices faced by DSP developers are outlined; and hints are given on the best solution.
LOW-RESOURCE DELAYLESS SUBBAND ADAPTIVE FILTER USING WEIGHTED OVERLAP-ADD
A delayless structure targeted for low-resource implementation is proposed to eliminate filterbank processing delays in subband adaptive filters (SAFs). Rather than using direct IFFT or polyphase filterbanks to transform the SAFs back into the time-domain, the proposed method utilizes a weighted overlap-add (WOLA) synthesis. Low-resource real-time implementations are targeted and as such do not involve long (as long as the echo plant) FFT or IFFT operations. Also, the proposed approach facilitates time distribution of the adaptive filter reconstruction calculations crucial for efficient real-time and hardware implementation. The method is implemented on an oversampled WOLA filterbank employed as part of an echo cancellation application. Evaluation results demonstrate that the proposed implementation outperforms conventional SAF systems since the signals used in actual adaptive filtering are not distorted by filterbank aliasing. The method is a good match for partial update adaptive algorithms since segments of the time-domain adaptive filter are sequentially reconstructed and updated.
A NEW PARALLEL IMPLEMENTATION FOR PARTICLE FILTERS AND ITS APPLICATION TO ADAPTIVE WAVEFORM DESIGN
Sequential Monte Carlo particle filters (PFs) are useful for estimating nonlinear non-Gaussian dynamic system parameters. As these algorithms are recursive, their real-time implementation can be computationally complex. In this paper, we analyze the bottlenecks in existing parallel PF algorithms, and we propose a new approach that integrates parallel PFs with independent Metropolis-Hastings (PPF-IMH) algorithms to improve root mean-squared estimation error performance. We implement the new PPF-IMH algorithm on a Xilinx Virtex-5 field programmable gate array (FPGA) platform. For a onedimensional problem and using 1,000 particles, the PPF-IMH architecture with four processing elements utilizes less than 5% Virtex-5 FPGA resources and takes 5.85 μs for one iteration. The algorithm performance is also demonstrated when designing the waveform for an agile sensing application.
Adaptive distributed noise reduction for speech enhancement in wireless acoustic sensor networks
An adaptive distributed noise reduction algorithm for speech enhancement is considered, which operates in a wireless acoustic sensor network where each node collects multiple microphone signals. In previous work, it was shown theoretically that for a stationary scenario, the algorithm provides the same signal estimators as the centralized multi-channel Wiener filter, while significantly compressing the data that is transmitted between the nodes. Here, we present simulation results of a fully adaptive implementation of the algorithm, in a non-stationary acoustic scenario with a moving speaker and two babble noise sources. The algorithm is implemented using a weighted overlap-add technique to reduce the overall input-output delay. It is demonstrated that good results can be obtained by estimating the required signal statistics with a long-term forgetting factor without downdating, even though the signal statistics change along with the iterative filter updates. It is also demonstrated that simultaneous node updating provides a significantly smoother and faster tracking performance compared to sequential node updating.
EFFICIENT MAPPING OF ADVANCED SIGNAL PROCESSING ALGORITHMS ON MULTI-PROCESSOR ARCHITECTURES
Modern microprocessor technology is migrating from simply increasing clock speeds on a single processor to placing multiple processors on a die to increase throughput and power performance in every generation. To utilize the potential of such a system, signal processing algorithms have to be efficiently parallelized so that the load can be distributed evenly among the multiple processing units. In this paper, we study several advanced deterministic and stochastic signal processing algorithms and their computation using multiple processing units. Specifically, we consider two commonly used time-frequency signal representations, the short-time Fourier transform and the Wigner distribution, and we demonstrate their parallelization with low communication overhead. We also consider sequential Monte Carlo estimation techniques such as particle filtering, and we demonstrate that its multiple processor implementation requires large data exchanges and thus a high communication overhead. We propose a modified mapping scheme that reduces this overhead at the expense of a slight loss in accuracy, and we evaluate the performance of the scheme for a state estimation problem with respect to accuracy and scalability.
Closing the gap: CPU and FPGA Trends in sustainable floating-point BLAS performance
Field programmable gate arrays (FPGAs) have long been an attractive alternative to microprocessors for computing tasks — as long as floating-point arithmetic is not required. Fueled by the advance of Moore’s Law, FPGAs are rapidly reaching sufficient densities to enhance peak floating-point performance as well. The question, however, is how much of this peak performance can be sustained. This paper examines three of the basic linear algebra subroutine (BLAS) functions: vector dot product, matrix-vector multiply, and matrix multiply. A comparison of microprocessors, FPGAs, and Reconfigurable Computing platforms is performed for each operation. The analysis highlights the amount of memory bandwidth and internal storage needed to sustain peak performance with FPGAs. This analysis considers the historical context of the last six years and is extrapolated for the next six years.
BLAS Comparison on FPGA, CPU and GPU
High Performance Computing (HPC) or scientific codes are being executed across a wide variety of computing platforms from embedded processors to massively parallel GPUs. We present a comparison of the Basic Linear Algebra Subroutines (BLAS) using double-precision floating point on an FPGA, CPU and GPU. On the CPU and GPU, we utilize standard libraries on state-of-the-art devices. On the FPGA, we have developed parameterized modular implementations for the dot product and Gaxpy or matrix-vector multiplication. In order to obtain optimal performance for any aspect ratio of the matrices, we have designed a high-throughput accumulator to perform an efficient reduction of floating point values. To support scalability to large data-sets, we target the BEE3 FPGA platform. We use performance and energy efficiency as metrics to compare the different platforms. Results show that FPGAs offer comparable performance as well as 2.7 to 293 times better energy efficiency for the test cases that we implemented on all three platforms.
Bilinear Transformation Made Easy
A formula is derived and demonstrated that is capable of directly generating digital filter coefficients from an analog filter prototype using the bilinear transformation. This formula obviates the need for any algebraic manipulation of the analog prototype filter and is ideal for use in embedded systems that must take in any general analog filter specification and dynamically generate digital filter coefficients directly usable in difference equations.
Method to Calculate the Inverse of a Complex Matrix using Real Matrix Inversion
This paper describes a simple method to calculate the invers of a complex matrix. The key element of the method is to use a matrix inversion, which is available and optimised for real numbers. Some actual libraries used for digital signal processing only provide highly optimised methods to calculate the inverse of a real matrix, whereas no solution for complex matrices are available, like in [1]. The presented algorithm is very easy to implement, while still much more efficient than for example the method presented in [2]. [1] Visual DSP++ 4.0 C/C++ Compiler and Library Manual for TigerSHARC Processors; Analog Devices; 2005. [2] W. Press, S.A. Teukolsky, W.T. Vetterling, B.R. Flannery; Numerical Recipes in C++, The art of scientific computing, Second Edition; p52 : “Complex Systems of Equations”;Cambridge University Press 2002.
Active control of automobile cabin noise with conventional and advanced speakers
Recently much research has focused on the control of enclosed sound fields, particularly in automobiles. Both Active Noise Control (ANC) and Active Structural Acoustic Control (ASAC) techniques are being applied to problems stemming from power train noise and road noise (noise due to the interaction of the tires with the surface of the road). Due to the low frequency characteristics of these noise problems, large acoustic sources are required to obtain efficient control of the sound field. This creates demand in the automobile industry for compact lightweight sources. This work is concerned with the application of active control to power train noise, as well as road noise in the interior cabin of a sport utility vehicle using advanced, compact lightweight piezoelectric acoustic sources. First, a test structure approximately the same size as the automobile was built to study the principles of active noise control in a cavity. A finite element model of the cavity was created in order to optimize the positions of the error sensors and the control sources. Experimental work was performed with the optimized actuator and sensor locations in order to validate the model, and draw conclusions regarding the conditions to obtain global control of the sound field. Second, a broad-band feedforward filtered-X LMS algorithm was used to control power train noise. Preliminary power train noise tests were conducted using arrangements of four microphones and up to four commercially available speakers for control. Attenuation of seven decibel (dB) at the error sensors was measured in the 40-500 Hz frequency band. The dimensions of the zone of quiet generated by the control were measured, and show that noise reductions were obtained for a large volume surrounding the error sensors. Next, advanced speakers were implemented for active control of power train noise. The results obtained with different arrangements of these speakers were very similar to those obtained with the commercially-available speakers. These advanced speakers use piezoelectric devices to induce the displacement of a speaker membrane, which radiates sound. Their lighter weight and compact dimensions are a significant advantage over conventional speakers, for their application in automobile. Third, preliminary results were obtained for active control of road noise. The controller used an optimized set of four reference signals to control the noise at one error sensor using one control source. Two sets of tests were conducted. The first set of tests was performed on a dynamometer, which simulates the effects of the road on the tires. The second set of tests was performed on a rough road. Reduction of two to four decibel of the sound pressure level at the error sensor was obtained between 100 and 200 Hz.
A NEW PARALLEL IMPLEMENTATION FOR PARTICLE FILTERS AND ITS APPLICATION TO ADAPTIVE WAVEFORM DESIGN
Sequential Monte Carlo particle filters (PFs) are useful for estimating nonlinear non-Gaussian dynamic system parameters. As these algorithms are recursive, their real-time implementation can be computationally complex. In this paper, we analyze the bottlenecks in existing parallel PF algorithms, and we propose a new approach that integrates parallel PFs with independent Metropolis-Hastings (PPF-IMH) algorithms to improve root mean-squared estimation error performance. We implement the new PPF-IMH algorithm on a Xilinx Virtex-5 field programmable gate array (FPGA) platform. For a onedimensional problem and using 1,000 particles, the PPF-IMH architecture with four processing elements utilizes less than 5% Virtex-5 FPGA resources and takes 5.85 μs for one iteration. The algorithm performance is also demonstrated when designing the waveform for an agile sensing application.
Efficient arithmetic for high speed DSP implementation on FPGAs
The author was sponsored by EnTegra Ltd, a company who develop hardware and software products and services for the real time implementation of DSP and RF systems. The field programmable gate array (FPGA) is being used increasingly in the field of DSP. This is due to the fact that the parallel computing power of such devices is ideal for today’s truly demanding DSP algorithms. Algorithms such as the QR-RLS update are computationally intensive and must be carried out at extremely high speeds (MHz). This means that the DSP processor is simply not an option. ASICs can be used but the expense of developing custom logic is prohibitive. The increased use of the FPGA in DSP means that there is a significant requirement for efficient arithmetic cores that utilises the resources on such devices. This thesis presents the research and development effort that was carried out to produce fixed point division and square root cores for use in a new Electronic Design Automation (EDA) tool for EnTegra, which is targeted at FPGA implementation of DSP systems. Further to this, a new technique for predicting the accuracy of CORDIC systems computing vector magnitudes and cosines/sines is presented. This work allows the most efficient CORDIC design for a specified level of accuracy to be found quickly and easily without the need to run lengthy simulations, as was the case before. The CORDIC algorithm is a technique using mainly shifts and additions to compute many arithmetic functions and is thus ideal for FPGA implementation.
Decoding Ogg Vorbis Audio with The C6416 DSP, using a custom made MDCT core on FPGA
Ogg Vorbis is a fairly new and growing audio format, often used for online distribution of music and internet radio stations for streaming audio. It is considered to be better than MP3 in both quality and compression and in the same league as for example AAC. In contrast with many other formats, like MP3 and AAC, Ogg Vorbis is patent and royalty free. The purpose of this thesis project was to investigate how the C6416 DSP processor and a Stratix II FPGA could be connected to each other and work together as co-processors and using an Ogg Vorbis decoder as implementation example. A fixed-point decoder called Tremor (developed by Xiph.Org the creator of the Vorbis I specification), has been ported to the DSP processor and an Ogg Vorbis player has been developed. Tremor was profiled before performing the software / hardware partitioning to decide what parts of the source code of Tremor that should be implemented in the FPGA to off-load and accelerate the DSP.
Specifying the Maximum Amplifier Noise When Driving an ADC
I recently learned an interesting rule of thumb regarding the use of an amplifier to drive the input of an analog to digital converter (ADC). The rule of thumb describes how to specify the maximum allowable noise power of the amplifier.
Design of a Scalable Polyphony-MIDI Synthesizer for a Low Cost DSP
In this thesis, the design of a music synthesizer implementing the Scalable Polyphony-MIDI soundset on a low cost DSP system is presented. First, the SP-MIDI standard and the target DSP platform are presented followed by review of commonly used synthesis techniques and their applicability to systems with limited computational and memory resources. Next, various oscillator and filter algorithms used in digital subtractive synthesis are reviewed in detail. Special attention is given to the aliasing problem caused by discontinuities in classical waveforms, such as sawtooth and pulse waves and existing methods for bandlimited waveform synthesis are presented. This is followed by review of established structures for computationally efficient time-varying filters. A novel digital structure is presented that decouples the cutoff and resonance controls. The new structure is based on the analog Korg MS-20 lowpass filter and is computationally very efficient and well suited for implementation on low bitdepth architectures. Finally, implementation issues are discussed with emphasis on the Differentiated Parabole Wave oscillator and MS-20 filter structures and the effects of limited computational capability and low bitdepth. This is followed by designs for several example instruments.
Real-time Motion Picture Restoration
Through age or misuse, motion picture films can develop damage in the form of dirt or scratches which detract from the quality of the film. Removal of these artifacts is a worthwhile process as it makes the films more visually attractive and extends the life of the material. In this thesis, various methods for detecting and concealing the effects of film damage are described. Appropriate algorithms are selected for implementation of a system, based on a TMS320C80 video processor, which can remove the effects of film defects using digital processing. The restoration process operates in real-time at video frame rates (30 frames per second). Details of the software implementation of this system are presented along with results from processing damaged film material. The effects of damage are significantly reduced after processing.
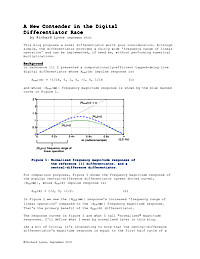
A New Contender in the Digital Differentiator Race
This blog proposes a novel differentiator worth your consideration. Although simple, the differentiator provides a fairly wide 'frequency range of linear operation' and can be implemented, if need be, without performing numerical multiplications.
A Prototype Laboratory Environment for Digital Signal Processing Using Simulink and a Texas Instrument DSP Device
Normally, when a model is designed from building blocks in Simulink, the simulation is performed within the Simulink environment. A test of the design in a real-time environment requires that source code is generated, compiled and downloaded to the target hardware. As a first attempt to bridge this software gap, this thesis describes and evaluates a prototype laboratory environment, which directly links Simulink to a Texas Instrument DSP device. The prototype system converts graphical models and makes available various real-time signal processing algorithms, such as adders, delays, FFTs, IIR filters and multipliers. Future work is to consider modification of the prototype to allow for feedback in the graphical models and to find an efficient way of handling signal processing algorithms where variable buffer lengths are required.