



A Review of Physical and Perceptual Feature Extraction Techniques for Speech, Music and Environmental Sounds
Endowing machines with sensing capabilities similar to those of humans is a prevalent quest in engineering and computer science. In the pursuit of making computers sense their surroundings, a huge effort has been conducted to allow machines and computers to acquire, process, analyze and understand their environment in a human-like way. Focusing on the sense of hearing, the ability of computers to sense their acoustic environment as humans do goes by the name of machine hearing. To achieve this ambitious aim, the representation of the audio signal is of paramount importance. In this paper, we present an up-to-date review of the most relevant audio feature extraction techniques developed to analyze the most usual audio signals: speech, music and environmental sounds. Besides revisiting classic approaches for completeness, we include the latest advances in the field based on new domains of analysis together with novel bio-inspired proposals. These approaches are described following a taxonomy that organizes them according to their physical or perceptual basis, being subsequently divided depending on the domain of computation (time, frequency, wavelet, image-based, cepstral, or other domains). The description of the approaches is accompanied with recent examples of their application to machine hearing related problems.
Specifying the Maximum Amplifier Noise When Driving an ADC
I recently learned an interesting rule of thumb regarding the use of an amplifier to drive the input of an analog to digital converter (ADC). The rule of thumb describes how to specify the maximum allowable noise power of the amplifier.
A Friendly Introduction to Compressed Sensing
Compared to other signal processing techniques, compressed sensing (or sparse sampling) has caught the interest of many mathematicians, electrical engineers, and computer scientists. The field of compressed sensing is still rapidly evolving. As most papers and textbooks about compressed sensing are at graduate level, the purpose of this paper is to offer a gentler exposure to compressed sensing from a mathematical perspective. By synthesizing my study on compressed sensing as an undergraduate, this thesis covers important concepts in CS such as coherence and restricted isometry property. Several key algorithms in compressed sensing will also be introduced with discussions of their stability, robustness, and performance. In the end, we investigate single-pixel camera as an example of real-world application of compressed sensing.
Algorithms, Architectures, and Applications for Compressive Video Sensing
The design of conventional sensors is based primarily on the Shannon-Nyquist sampling theorem, which states that a signal of bandwidth W Hz is fully determined by its discrete-time samples provided the sampling rate exceeds 2W samples per second. For discrete-time signals, the Shannon-Nyquist theorem has a very simple interpretation: the number of data samples must be at least as large as the dimensionality of the signal being sampled and recovered. This important result enables signal processing in the discrete-time domain without any loss of information. However, in an increasing number of applications, the Shannon-Nyquist sampling theorem dictates an unnecessary and often prohibitively high sampling rate. (See Box 1 for a derivation of the Nyquist rate of a time-varying scene.) As a motivating example, the high resolution of the image sensor hardware in modern cameras reflects the large amount of data sensed to capture an image. A 10-megapixel camera, in effect, takes 10 million measurements of the scene. Yet, almost immediately after acquisition, redundancies in the image are exploited to compress the acquired data significantly, often at compression ratios of 100:1 for visualization and even higher for detection and classification tasks. This example suggests immense wastage in the overall design of conventional cameras.
Use Matlab Function pwelch to Find Power Spectral Density - or Do It Yourself
In this article, I'll present some examples to show how to use pwelch. You can also "do it yourself", i.e. compute spectra using the Matlab fft or other fft function. As examples, the appendix provides two demonstration mfiles; one computes the spectrum without DFT averaging, and the other computes the spectrum with DFT averaging.
Fully Programmable LDPC Decoder Hardware Architectures
In recent years, the amount of digital data which is stored and transmitted for private and public usage has increased considerably. To allow a save transmission and storage of data despite of error-prone transmission media, error correcting codes are used. A large variety of codes has been developed, and in the past decade low-density parity-check (LDPC) codes which have an excellent error correction performance became more and more popular. Today, low-density parity-check codes have been adopted for several standards, and efficient decoder hardware architectures are known for the chosen structured codes. However, the existing decoder designs lack flexibility as only few structured codes can be decoded with one decoder chip. In consequence, different codes require a redesign of the decoder, and few solutions exist for decoding of codes which are not quasi-cyclic or which are unstructured. In this thesis, three different approaches are presented for the implementation of fully programmable LDPC decoders which can decode arbitrary LDPC codes. As a design study, the first programmable decoder which uses a heuristic mapping algorithm is realized on an field-programmable gate array (FPGA), and error correction curves are measured to verify the correct functionality. The main contribution of this thesis lies in the development of the second and the third architecture and an appropriate mapping algorithm. The proposed fully programmable decoder architectures use one-phase message passing and layered decoding and can decode arbitrary LDPC codes using an optimum mapping and scheduling algorithm. The presented programmable architectures are in fact generalized decoder architectures from which the known decoders architectures for structured LDPC codes can be derived.
Introduction to Digital Signal Processing
Nice slides introducing Digital Signal Processing.
Audio Time-Scale Modification
Audio time-scale modification is an audio effect that alters the duration of an audio signal without affecting its perceived local pitch and timbral characteristics. There are two broad categories of time-scale modification algorithms, time-domain and frequency-domain. The computationally efficient time-domain techniques produce high quality results for single pitched signals such as speech, but do not cope well with more complex signals such as polyphonic music. The less efficient frequencydomain techniques have proven to be more robust and produce high quality results for a variety of signals; however they introduce a reverberant artefact into the output. This dissertation focuses on incorporating aspects of time-domain techniques into frequency-domain techniques in an attempt to reduce the presence of the reverberant artefact and improve upon computational demands. From a review of prior work it was found that there are a number of time-domain algorithms available and that the choice of algorithm parameters varies considerably in the literature. This finding prompted an investigation into the effects of the choice of parameters and a comparison of the various techniques employed in terms of computational requirements and output quality. The investigation resulted in the derivation of an efficient and flexible parameter set for use within time-domain implementations. Of the available frequency-domain approaches the phase vocoder and timedomain/ subband techniques offer an efficiency and robustness advantage over sinusoidal modelling and iterative phase update techniques, and as such were identified as suitable candidates for the provision of a framework for further investigation. Following from this observation, improvements in the quality produced by time-domain/subband techniques are realised through the use of a bark based subband partitioning approach and effective subband synchronisation techniques. In addition, computational and output quality improvements within a phase vocoder implementation are achieved by taking advantage of a certain level of flexibility in the choice of phase within such an implementation. The phase flexibility established is used to push or pull phase values into a phase coherent state. Further improvements are realised by incorporating features of time-domain algorithms into the system in order to provide a ‘good’ initial set of phase estimates; the transition to ‘perfect’ phase coherence is significantly reduced through this scheme, thereby improving the overall output quality produced. The result is a robust and efficient time-scale modification algorithm which draws upon various aspects of a number of general approaches to time-scale modification.
Auditory System for a Mobile Robot
The auditory system of living creatures provides useful information about the world, such as the location and interpretation of sound sources. For humans, it means to be able to focus one's attention on events, such as a phone ringing, a vehicle honking, a person taking, etc. For those who do not suffer from hearing impairments, it is hard to imagine a day without being able to hear, especially in a very dynamic and unpredictable world. Mobile robots would also benefit greatly from having auditory capabilities. In this thesis, we propose an artificial auditory system that gives a robot the ability to locate and track sounds, as well as to separate simultaneous sound sources and recognising simultaneous speech. We demonstrate that it is possible to implement these capabilities using an array of microphones, without trying to imitate the human auditory system. The sound source localisation and tracking algorithm uses a steered beamformer to locate sources, which are then tracked using a multi-source particle filter. Separation of simultaneous sound sources is achieved using a variant of the Geometric Source Separation (GSS) algorithm, combined with a multisource post-filter that further reduces noise, interference and reverberation. Speech recognition is performed on separated sources, either directly or by using Missing Feature Theory (MFT) to estimate the reliability of the speech features. The results obtained show that it is possible to track up to four simultaneous sound sources, even in noisy and reverberant environments. Real-time control of the robot following a sound source is also demonstrated. The sound source separation approach we propose is able to achieve a 13.7 dB improvement in signal-to-noise ratio compared to a single microphone when three speakers are present. In these conditions, the system demonstrates more than 80% accuracy on digit recognition, higher than most human listeners could obtain in our small case study when recognising only one of these sources. All these new capabilities will allow humans to interact more naturally with a mobile robot in real life settings.
Sum of Two Equal-Frequency Sinusoids
The sum of two equal-frequency real sinusoids is itself a single real sinusoid. However, the exact equations for all the various forms of that single equivalent sinusoid are difficult to find in the signal processing literature. Here we provide those equations.
Using the DFT as a Filter: Correcting a Misconception
I have read, in some of the literature of DSP, that when the discrete Fourier transform (DFT) is used as a filter the process of performing a DFT causes an input signal's spectrum to be frequency translated down to zero Hz (DC). I can understand why someone might say that, but I challenge that statement as being incorrect. Here are my thoughts.
Specifying the Maximum Amplifier Noise When Driving an ADC
I recently learned an interesting rule of thumb regarding the use of an amplifier to drive the input of an analog to digital converter (ADC). The rule of thumb describes how to specify the maximum allowable noise power of the amplifier.
Towards Efficient and Robust Automatic Speech Recognition: Decoding Techniques and Discriminative Training
Automatic speech recognition has been widely studied and is already being applied in everyday use. Nevertheless, the recognition performance is still a bottleneck in many practical applications of large vocabulary continuous speech recognition. Either the recognition speed is not sufficient, or the errors in the recognition result limit the applications. This thesis studies two aspects of speech recognition, decoding and training of acoustic models, to improve speech recognition performance in different conditions.
Adaptive Algorithms in Digital Signal Processing - Overview, Theory and Applications
An Introduction To Compressive Sampling
This article surveys the theory of compressive sensing, also known as compressed sensing or CS, a novel sensing/sampling paradigm that goes against the common wisdom in data acquisition.
Introduction to Compressed Sensing
Chapter 1 of the book: "Compressed Sensing: Theory and Applications".
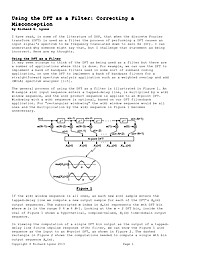
Using the DFT as a Filter: Correcting a Misconception
I have read, in some of the literature of DSP, that when the discrete Fourier transform (DFT) is used as a filter the process of performing a DFT causes an input signal's spectrum to be frequency translated down to zero Hz (DC). I can understand why someone might say that, but I challenge that statement as being incorrect. Here are my thoughts.
Voice Activity Detection. Fundamentals and Speech Recognition System Robustness
An important drawback affecting most of the speech processing systems is the environmental noise and its harmful effect on the system performance. Examples of such systems are the new wireless communications voice services or digital hearing aid devices. In speech recognition, there are still technical barriers inhibiting such systems from meeting the demands of modern applications. Numerous noise reduction techniques have been developed to palliate the effect of the noise on the system performance and often require an estimate of the noise statistics obtained by means of a precise voice activity detector (VAD). Speech/non-speech detection is an unsolved problem in speech processing and affects numerous applications including robust speech recognition, discontinuous transmission, real-time speech transmission on the Internet or combined noise reduction and echo cancellation schemes in the context of telephony. The speech/non-speech classification task is not as trivial as it appears, and most of the VAD algorithms fail when the level of background noise increases. During the last decade, numerous researchers have developed different strategies for detecting speech on a noisy signal and have evaluated the influence of the VAD effectiveness on the performance of speech processing systems. Most of the approaches have focussed on the development of robust algorithms with special attention being paid to the derivation and study of noise robust features and decision rules. The different VAD methods include those based on energy thresholds, pitch detection, spectrum analysis, zero-crossing rate, periodicity measure, higher order statistics in the LPC residual domain or combinations of different features. This chapter shows a comprehensive approximation to the main challenges in voice activity detection, the different solutions that have been reported in a complete review of the state of the art and the evaluation frameworks that are normally used. The application of VADs for speech coding, speech enhancement and robust speech recognition systems is shown and discussed. Three different VAD methods are described and compared to standardized and recently reported strategies by assessing the speech/non-speech discrimination accuracy and the robustness of speech recognition systems.
Sum of Two Equal-Frequency Sinusoids
The sum of two equal-frequency real sinusoids is itself a single real sinusoid. However, the exact equations for all the various forms of that single equivalent sinusoid are difficult to find in the signal processing literature. Here we provide those equations.
Fully Programmable LDPC Decoder Hardware Architectures
In recent years, the amount of digital data which is stored and transmitted for private and public usage has increased considerably. To allow a save transmission and storage of data despite of error-prone transmission media, error correcting codes are used. A large variety of codes has been developed, and in the past decade low-density parity-check (LDPC) codes which have an excellent error correction performance became more and more popular. Today, low-density parity-check codes have been adopted for several standards, and efficient decoder hardware architectures are known for the chosen structured codes. However, the existing decoder designs lack flexibility as only few structured codes can be decoded with one decoder chip. In consequence, different codes require a redesign of the decoder, and few solutions exist for decoding of codes which are not quasi-cyclic or which are unstructured. In this thesis, three different approaches are presented for the implementation of fully programmable LDPC decoders which can decode arbitrary LDPC codes. As a design study, the first programmable decoder which uses a heuristic mapping algorithm is realized on an field-programmable gate array (FPGA), and error correction curves are measured to verify the correct functionality. The main contribution of this thesis lies in the development of the second and the third architecture and an appropriate mapping algorithm. The proposed fully programmable decoder architectures use one-phase message passing and layered decoding and can decode arbitrary LDPC codes using an optimum mapping and scheduling algorithm. The presented programmable architectures are in fact generalized decoder architectures from which the known decoders architectures for structured LDPC codes can be derived.
Model Signal Impairments at Complex Baseband
In this article, we develop complex-baseband models for several signal impairments: interfering carrier, multipath, phase noise, and Gaussian noise. To provide concrete examples, we'll apply the impairments to a QAM system. The impairment models are Matlab functions that each use at most seven lines of code. Although our example system is QAM, the models can be used for any complex-baseband signal.
Introduction to Compressed Sensing
Chapter 1 of the book: "Compressed Sensing: Theory and Applications".
Digital Signal Processing Maths
Modern digital signal processing makes use of a variety of mathematical techniques. These techniques are used to design and understand efficient filters for data processing and control.
Using the DFT as a Filter: Correcting a Misconception
I have read, in some of the literature of DSP, that when the discrete Fourier transform (DFT) is used as a filter the process of performing a DFT causes an input signal's spectrum to be frequency translated down to zero Hz (DC). I can understand why someone might say that, but I challenge that statement as being incorrect. Here are my thoughts.
A NEW PARALLEL IMPLEMENTATION FOR PARTICLE FILTERS AND ITS APPLICATION TO ADAPTIVE WAVEFORM DESIGN
Sequential Monte Carlo particle filters (PFs) are useful for estimating nonlinear non-Gaussian dynamic system parameters. As these algorithms are recursive, their real-time implementation can be computationally complex. In this paper, we analyze the bottlenecks in existing parallel PF algorithms, and we propose a new approach that integrates parallel PFs with independent Metropolis-Hastings (PPF-IMH) algorithms to improve root mean-squared estimation error performance. We implement the new PPF-IMH algorithm on a Xilinx Virtex-5 field programmable gate array (FPGA) platform. For a onedimensional problem and using 1,000 particles, the PPF-IMH architecture with four processing elements utilizes less than 5% Virtex-5 FPGA resources and takes 5.85 μs for one iteration. The algorithm performance is also demonstrated when designing the waveform for an agile sensing application.
Audio Time-Scale Modification
Audio time-scale modification is an audio effect that alters the duration of an audio signal without affecting its perceived local pitch and timbral characteristics. There are two broad categories of time-scale modification algorithms, time-domain and frequency-domain. The computationally efficient time-domain techniques produce high quality results for single pitched signals such as speech, but do not cope well with more complex signals such as polyphonic music. The less efficient frequencydomain techniques have proven to be more robust and produce high quality results for a variety of signals; however they introduce a reverberant artefact into the output. This dissertation focuses on incorporating aspects of time-domain techniques into frequency-domain techniques in an attempt to reduce the presence of the reverberant artefact and improve upon computational demands. From a review of prior work it was found that there are a number of time-domain algorithms available and that the choice of algorithm parameters varies considerably in the literature. This finding prompted an investigation into the effects of the choice of parameters and a comparison of the various techniques employed in terms of computational requirements and output quality. The investigation resulted in the derivation of an efficient and flexible parameter set for use within time-domain implementations. Of the available frequency-domain approaches the phase vocoder and timedomain/ subband techniques offer an efficiency and robustness advantage over sinusoidal modelling and iterative phase update techniques, and as such were identified as suitable candidates for the provision of a framework for further investigation. Following from this observation, improvements in the quality produced by time-domain/subband techniques are realised through the use of a bark based subband partitioning approach and effective subband synchronisation techniques. In addition, computational and output quality improvements within a phase vocoder implementation are achieved by taking advantage of a certain level of flexibility in the choice of phase within such an implementation. The phase flexibility established is used to push or pull phase values into a phase coherent state. Further improvements are realised by incorporating features of time-domain algorithms into the system in order to provide a ‘good’ initial set of phase estimates; the transition to ‘perfect’ phase coherence is significantly reduced through this scheme, thereby improving the overall output quality produced. The result is a robust and efficient time-scale modification algorithm which draws upon various aspects of a number of general approaches to time-scale modification.
Through-Wall Imaging with UWB Radar System
Motivation: A man was interested in knowing of unknown from the very beginning of the human history. Our human eyes help us to investigate our environment by reflection of light. However, wavelengths of visible light allows transparent view through only a very small kinds of materials. On the other hand, Ultra WideBand (UWB) electromagnetic waves with frequencies of few Gigahertz are able to penetrate through almost all types of materials around us. With some sophisticated methods and a piece of luck we are able to investigate what is behind opaque walls. Rescue and security of the people is one of the most promising fields for such applications. Rescue: Imagine how useful can be information about interior of the barricaded building with terrorists and hostages inside for a policemen. The tactics of police raid can be build up on realtime information about ground plan of the room and positions of big objects inside. How useful for the firemen can be information about current interior state of the room before they get inside? Such hazardous environment, full of smoke with zero visibility, is very dangerous and each additional information can make the difference between life and death. Security: Investigating objects through plastic, rubber, dress or other nonmetallic materials could be highly useful as an additional tool to the existing x-ray scanners. Especially it could be used for scanning baggage at the airport, truckloads on borders, dangerous boxes, etc.
A Subspace Based Approach to the Design, Implementation and Validation of Algorithms for Active Vibration Isolation Control
Vibration isolation endeavors to reduce the transmission of vibration energy from one structure (the source) to another (the receiver), to prevent undesirable phenomena such as sound radiation. A well-known method for achieving this is passive vibration isolation (PVI). In the case of PVI, mounts are used - consisting of springs and dampers - to connect the vibrating source to the receiver. The stiffness of the mount determines the fundamental resonance frequency of the mounted system and vibrations with a frequency higher than the fundamental resonance frequency are attenuated. Unfortunately, however, other design requirements (such as static stability) often impose a minimum allowable stiffness, thus limiting the achievable vibration isolation by passive means. A more promising method for vibration isolation is hybrid vibration isolation control. This entails that, in addition to PVI, an active vibration isolation control (AVIC) system is used with sensors, actuators and a control system that compensates for vibrations in the lower frequency range. Here, the use of a special form of AVIC using statically determinate stiff mounts is proposed. The mounts establish a statically determinate system of high stiffness connections in the actuated directions and of low stiffness connections in the unactuated directions. The latter ensures PVI in the unactuated directions. This approach is called statically determinate AVIC (SD-AVIC). The aim of the control system is to produce antidisturbance forces that counteract the disturbance forces stemming from the source. Using this approach, the vibration energy transfer from the source to the receiver is blocked in the mount due to the anti-forces. This thesis deals with the design of controllers generating the anti-forces by applying techniques that are commonly used in the field of signal processing. The control approaches - that are model-based - are both adaptive and fixed gain and feedforward and feedback oriented. The control approaches are validated using two experimental vibration isolation setups: a single reference single actuator single error sensor (SR-SISO) setup and a single reference input multiple actuator input multiple error sensor output (SR-MIMO) setup. Finding a plant model can be a problem. This is solved by using a black-box modelling strategy. The plants are identified using subspace model identification. It is shown that accurate linear models can be found in a straightforward manner by using small batches of recorded (sampled) time-domain data only. Based on the identified models, controllers are designed, implemented and validated. Due to resonance in mechanical structures, adaptive SD-AVIC systems are often hampered by slow convergence of the controller coefficients. In general, it is desirable that the SD-AVIC system yields fast optimum performance after it is switched on. To achieve this result and speed up the convergence of the adaptive controller coefficients, the so-called inverse outer factor model is included in the adaptive control scheme. The inner/outer factorization, that has to be performed to obtain the inverse outer factor model, is completely determined in state space to enable a numerically robust computation. The inverse outer factor model is also incorporated in the control scheme as a state space model. It is found that fast adaptation of the controller coefficients is possible. Controllers are designed, implemented and validated to suppress both narrowband and broadband disturbances. Scalar regularization is used to prevent actuator saturation and an unstable closed loop. In order to reduce the computational load of the controllers, several steps are taken including controller order reduction and implementation of lower order models. It is found that in all experiments the simulation and real-time results correspond closely for both the fixed gain and adaptive control situation. On the SR-SISO setup, reductions up to 5.0 dB are established in real-time for suppressing a broadband disturbance output (0-2 kHz) using feedback-control. On the SR-MIMO vibration isolation setup, using feedforward-control reductions of broadband disturbances (0-1 kHz) of 9.4 dB are established in real-time. Using feedback-control, reductions are established up to 3.5 dB in real-time (0-1 kHz). In case of the SR-MIMO setup, the values for the reduction are obtained by averaging the reductions obtained in all sensor outputs. The results pave the way for the next generation of algorithms for SD-AVIC.